Project Info
Inspiration
I have always been fascinated by scientific papers. They contain years of work, difficult ideas, carefully constructed models, and discoveries that can change how we understand the world. But something has always bothered me: after all that work, the result is usually compressed into a static document. A paper may describe a dynamic biological system, a physical process, or a mathematical model—but the reader still sees fixed equations, screenshots, and plots. Even when the underlying system is alive with movement and interaction, the publication itself remains frozen. An equation such as $$ \dot{x}_1 = \frac{\beta}{1+x_3^n} - \gamma x_1 $$ contains behavior. It can oscillate, stabilize, diverge, or react dramatically to a changed parameter. Yet most readers never get to experience that behavior directly. This creates a gap between reading research and understanding research. Students may recognize the symbols without developing intuition. Educators must rebuild demonstrations manually. Reviewers have to trace equations, parameters, figures, and supplementary material across many pages. Researchers often spend time reconstructing models before they can even begin exploring them. I built PaperAlive because I wanted scientific work to feel more tangible. My goal was not to create attractive animations loosely inspired by a paper. I wanted something much stricter: a system that could transform supported scientific papers into interactive experiments while keeping every equation, parameter, control, curve, and result connected to its original evidence. The paper should remain the source of truth. The experiment should make that truth explorable. That idea became PaperAlive: research you can touch—and audit.
What it does
PaperAlive is a Codex-native scientific compiler that turns supported scientific papers into evidence-linked, scientifically verified interactive experiments. It is deliberately not a free-form visualization generator. A convincing animation is easy to create; a trustworthy scientific representation is much harder. PaperAlive follows a compiler-style pipeline: Extract evidence from a text-based PDF, Markdown document, LaTeX source, or supported data supplement. Evaluate compatibility before attempting to create an experiment. Resolve equations, symbols, parameters, units, initial conditions, domains, and source locations. Compile the evidence into PAER, the typed PaperAlive Experiment Representation. Run structural, semantic, dimensional, provenance, numerical, convergence, and invariant checks. Execute an independent Python reference calculation. Compare the result against a predeclared paper result or scientific invariant when one is available. Select a trusted visualization template from an allowlisted renderer registry. Build a self-contained offline Experiment Studio. Start a local server and return an immediately usable URL. If a paper does not contain enough information for a defensible model, PaperAlive does not guess. It returns a compatibility report explaining exactly what is missing. Possible outcomes include: SUPPORTED_AUTOMATIC SUPPORTED_WITH_REVIEW ILLUSTRATIVE_ONLY UNSUPPORTED Missing parameters, undefined symbols, incompatible units, absent initial conditions, unresolved evidence, unsupported mathematics, or unstable numerical results are hard failures—not details to be silently invented. A concrete demonstration: the repressilator The main PaperAlive demonstration uses the open-access paper “Data-driven model discovery and model selection for noisy biological systems” by Wu, McDermott, and MacLean. The paper describes a simplified repressilator: three proteins connected through a negative feedback loop. Each protein suppresses the next, producing oscillations that eventually settle into a stable limit cycle. PaperAlive turns that static model into: synchronized time-series plots of all three protein concentrations; a labelled three-dimensional mathematical phase space; interactive controls restricted to evidenced values and ranges; an equation walkthrough; comparison with the paper baseline; an independent numerical reference calculation; a visible trust status; and an evidence thread connecting every quantitative element back to the relevant paper location. A user can select a parameter and immediately inspect its source. Selecting a curve, equation, or phase-space object reveals the evidence behind it. Selecting the evidence returns the user to every connected representation. The visualization is therefore not separate from the scientific record. It is an interface into it. Supported experiment types The current version contains three carefully bounded scientific adapters: ODE systems: deterministic models with one to three state variables, shown through time series, phase portraits, and labelled three-state phase spaces. Particle systems: deterministic physical or conceptual particles with trajectories, forces, vectors, scale semantics, and invariant checks. Scalar fields: evidenced one-, two-, or three-dimensional fields represented through heatmaps, contours, and surfaces. PaperAlive chooses the representation from validated model semantics. It does not force every paper into 3D. Who it is for PaperAlive is designed for: students, who need to develop intuition instead of only memorizing equations; educators, who want interactive, source-grounded demonstrations without rebuilding every model manually; researchers, who want a faster path from publication to exploration; reviewers, who need to inspect whether equations, parameters, and reported results agree; science communicators, who want engagement without sacrificing scientific honesty; and curious readers, who want to experience what a paper actually describes.
How we built it
I built PaperAlive with Codex and GPT-5.6 as an active engineering partner during OpenAI Build Week. Codex was not used only to generate isolated code snippets. I used it to reason across the entire system: scientific requirements, schema design, security boundaries, numerical methods, frontend behavior, accessibility, test strategy, plugin packaging, and documentation. I defined the central principle early: PaperAlive must fail honestly before it visualizes dishonestly. Codex helped translate that principle into concrete architecture, validation rules, negative test cases, and implementation decisions across the repository. A typed scientific intermediate representation At the center of PaperAlive is PAER, the PaperAlive Experiment Representation. PAER is defined by one canonical JSON Schema. It contains: source artifacts and cryptographic hashes; precise provenance anchors; quantities and units; equations represented as a closed abstract syntax tree; parameters and initial or boundary conditions; model and solver configuration; experiment controls; visualization mappings; validation evidence; trust status; warnings and limitations. TypeScript types are generated from the same schema used by Python validation, preventing the frontend and compiler from silently developing different ideas of what an experiment means. Equations are never stored as executable code. PaperAlive uses a closed, allowlisted mathematical AST and never calls eval, executes author scripts, runs notebook cells, or accepts arbitrary shaders or JavaScript from a paper. Independent scientific execution The interactive browser calculation and the scientific reference calculation are deliberately separate. The frontend uses deterministic TypeScript solvers running inside a Web Worker. The reference path uses Python with NumPy and SciPy. Results are compared using declared tolerances, convergence behavior, paper targets, or appropriate invariants. This separation matters: if the UI and the reference calculation shared the same implementation, they could reproduce the same mistake. Camera position, framerate, interpolation, display sampling, and visual scaling are downstream presentation choices. They cannot feed back into the scientific state. Trusted rendering Validated PAER semantics are mapped to fixed renderer templates: MathJax for accessible equations; Plotly for quantitative charts, fields, contours, and surfaces; React Three Fiber and Three.js for physical particle trajectories and labelled mathematical phase spaces; PDF.js for local evidence inspection. Unsupported mappings produce an evidence report rather than an improvised scene. Offline by design The generated Experiment Studio is a static React application built with TypeScript and Vite. A completed experiment requires: no runtime API key; no OpenAI SDK; no backend; no user login; no runtime model call; no CDN; and no external font service. After compilation, PaperAlive packages the experiment and starts a verified loopback-only server on 127.0.0.1. The user receives a clickable local URL and an exact command for stopping the server. This makes the resulting experiment portable, inspectable, private, and suitable for classrooms, review workflows, or sensitive local research environments.
Challenges we ran into
Making AI useful without allowing it to invent science The biggest challenge was deciding where AI reasoning belongs—and where it must stop. Codex is excellent at reading context and connecting evidence across a paper. But scientific software cannot accept a value simply because it looks plausible. The solution was a strict boundary: Codex performs evidence-aware semantic interpretation, while deterministic local code enforces the schema, units, symbols, domains, provenance, numerical behavior, resource limits, and renderer selection. Any assumption required to make the model run must be explicitly supported. Otherwise, the quantitative build stops. Treating provenance as part of the product It was not enough to store a citation somewhere in a report. Every slider, equation, axis, curve, initial condition, comparison target, and quantitative spatial object needed a stable connection to evidence. That required provenance to become a first-class part of the data model and the interface—not an afterthought. Separating “looks correct” from “is verified” Scientific visualization can be dangerously persuasive. A smooth curve and polished 3D scene may hide incorrect equations, broken units, or unstable numerics. PaperAlive therefore validates before rendering. The weakest critical gate determines the visible trust status, and warnings remain visible even when other checks pass. Supporting useful papers without pretending to support every paper Many scientific papers cannot be converted honestly from the publication alone. They may omit parameters, depend on unavailable author code, use unsupported numerical methods, or describe qualitative work without an executable model. Instead of hiding those limitations, PaperAlive makes refusal a successful outcome. A precise evidence-backed explanation is more valuable than a fabricated experiment. Building a complete offline experience The final viewer had to remain interactive without a backend or runtime model connection. That required local rendering, Web Worker simulation, safe package import and export, bundled mathematical accessibility, local PDF evidence viewing, and a secure local preview server.
Accomplishments we're proud of
I am especially proud that PaperAlive is a working end-to-end system rather than a visual prototype. The project now includes: an installable Codex plugin with a complete $paperalive workflow; paper and supplement extraction with source hashes and location anchors; a canonical typed scientific representation; structural, semantic, dimensional, provenance, numerical, convergence, invariant, and reproduction gates; independent Python and TypeScript scientific implementations; three bounded model adapters; a closed renderer registry; an offline interactive Experiment Studio; local evidence inspection and bidirectional provenance navigation; safe package import and export; a verified local preview server; a real open-access paper demonstration; synthetic ground-truth benchmarks for particle and scalar-field behavior; and a complete release gate covering linting, types, security architecture, unit tests, scientific evaluations, browser tests, accessibility, offline operation, and plugin validation. I am also proud of what PaperAlive refuses to do. It does not turn every paper into a generic 3D animation. It does not execute arbitrary author code. It does not silently choose missing values. It does not claim real-world validation when only numerical verification was performed. Scientific honesty is not a limitation of the product. It is the product.
What we learned
The most important thing I learned is that trust can be an interaction design feature. A provenance link does not have to live in a forgotten appendix. It can be something the user touches. Validation does not have to be a hidden build step. It can be visible and understandable. Limitations do not weaken an experiment when they are communicated clearly; they make the result more useful. I also learned that interactivity changes how a reader approaches a model. Once an equation can be explored, people naturally begin asking better questions: What changes if this parameter moves? Which behavior comes directly from the paper? Which values were derived? Does the numerical result converge? Where did this curve come from? What would make this model unsupported? Codex was particularly powerful for a project like this because PaperAlive crosses many technical boundaries. It combines document processing, scientific computing, type systems, security, frontend visualization, plugin architecture, and accessibility. Codex helped maintain context across those layers while continuously testing whether the implementation still respected the original scientific principles. The project reinforced a simple idea for me: The most impressive scientific visualization is not the one that looks the most complex. It is the one that earns the reader's trust.
What's next
for PaperAlive The current version establishes a strict and testable foundation. Next, I want to expand PaperAlive without weakening that foundation. Planned directions include: More isolated scientific adapters for additional model classes, each with its own evidence requirements, numerical verification, resource limits, and trusted renderers. A larger open benchmark library of papers with reproducible interactive experiments and clearly documented compatibility decisions. Author workflows that allow researchers to publish a PAER package alongside a traditional paper. Reviewer mode for comparing equations, parameter tables, code outputs, and claimed results during peer review. Classroom mode with guided questions, parameter challenges, accessible explanations, and instructor-defined exploration boundaries. Continuous reproducibility checks that can detect when dependencies, source artifacts, or numerical behavior change. Shareable offline experiment packages that preserve evidence, validation reports, results, and the interactive viewer as one auditable artifact. Community extension points for new adapters and renderers that must pass the same scientific and security contracts before they can be trusted. My long-term vision is for interactive, auditable experiments to become a normal companion to scientific publishing. A PDF should not be the end of a scientific idea. It should be the beginning of an exploration. PaperAlive gives scientific papers a pulse—without disconnecting them from the evidence that makes them trustworthy.
PaperAlive — A Codex Plugin
Turn scientific papers into experiments you can touch — and audit.


Scientific papers are full of equations, parameters, initial conditions and results—but they are still usually experienced as static pages. PaperAlive is a Codex-native scientific compiler that turns supported papers into interactive, evidence-linked experiments.
It does not invent missing science and it does not force every paper into a flashy 3D scene. It extracts the evidence, checks whether the paper is computationally representable, builds a typed experiment model, runs deterministic scientific gates, reproduces supported results and opens a local interactive viewer.
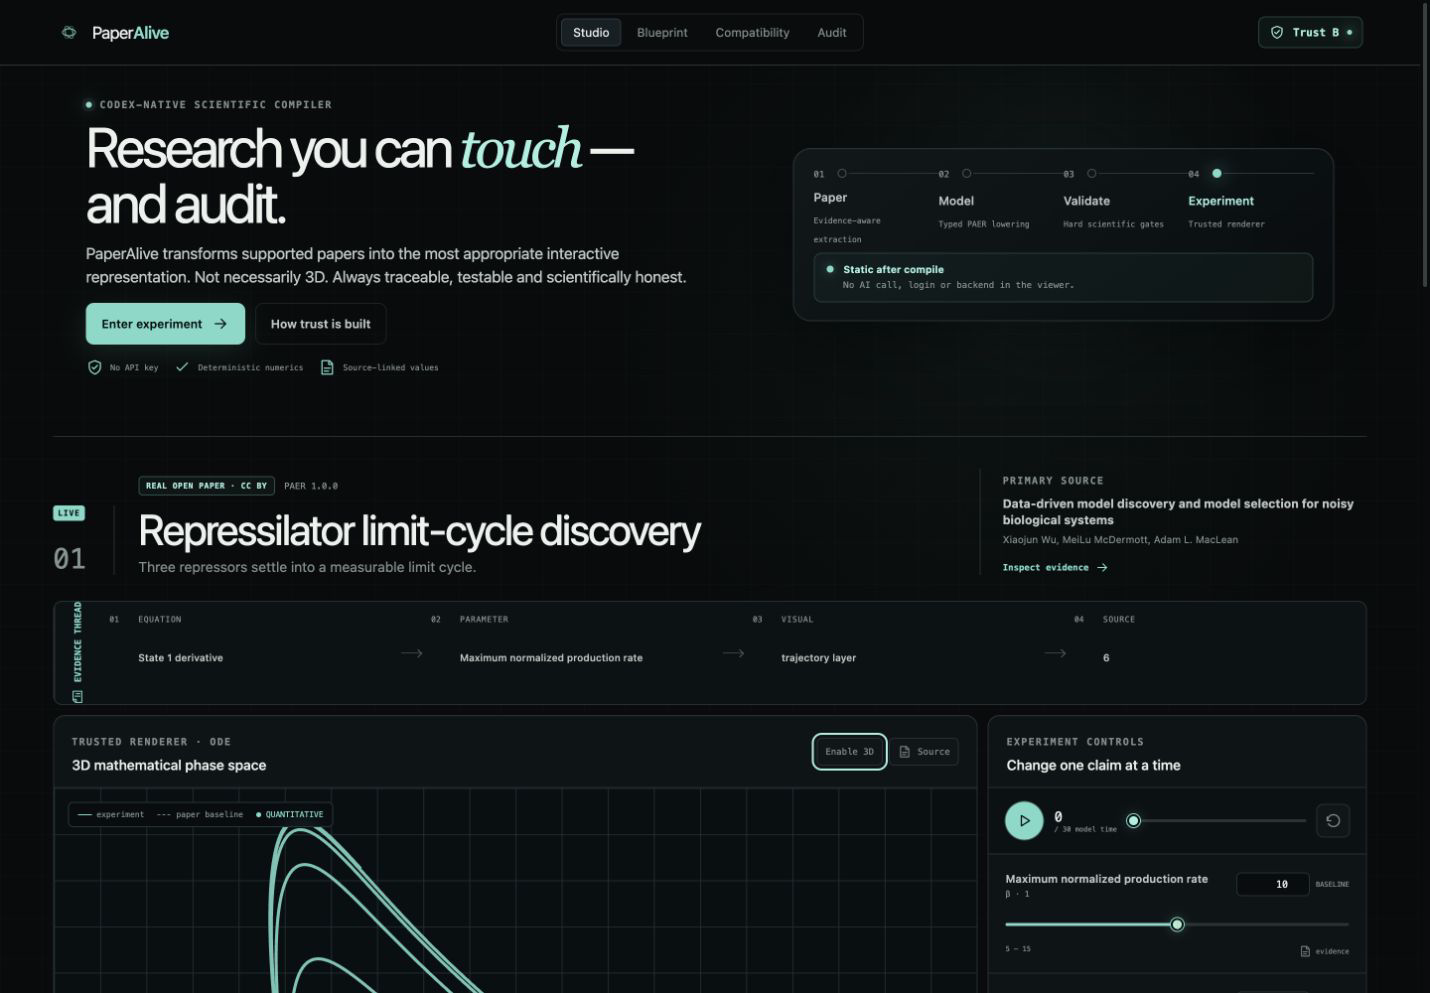
Why PaperAlive matters
A conventional visualization can make a paper easier to look at. PaperAlive is designed to make it easier to understand, test and question:
- change a reported parameter and immediately see its effect;
- compare a variation against the paper baseline;
- follow every quantitative control back to a source location;
- inspect equations, units, assumptions and validation evidence;
- export the experiment as a static offline package;
- receive an explicit refusal when the source cannot support an honest model.
The result is useful for students, educators, reviewers, researchers and curious readers who want to move from reading a claim to interacting with the model behind it.
Install in Codex
Requirements
- Codex with plugin support
- Python 3.12 or newer
- internet access once to install the pinned Python packages
- no API key, backend, account or Node.js build step
1. Add the public marketplace
codex plugin marketplace add victus17/paperalive-codex-plugin
2. Install PaperAlive
codex plugin add paperalive@paperalive
3. Start a new Codex task
Attach a text-based scientific PDF and write:
$paperalive Compile this paper into a validated interactive experiment.
PaperAlive returns the exact compatibility and trust status, the evidence-linked PAER, validation reports, reference results, a static site, an offline package and—after a successful compilation—a verified local URL such as http://127.0.0.1:43127/.
Try the included Repressilator paper
This repository includes a real open-access paper and a reviewed PAER example:
Clone the repository, attach the PDF from examples/repressilator/ to a new Codex task and use the prompt above. The paper contains a three-protein repressilator model with an oscillating limit cycle—an ideal example of how a static biological system can become an explorable experiment.
The source is Wu, McDermott & MacLean (2025), Data-driven model discovery and model selection for noisy biological systems, PLOS Computational Biology, DOI 10.1371/journal.pcbi.1012762, distributed under CC BY 4.0. Full attribution and the verified source hash are in examples/repressilator/ATTRIBUTION.md.
How it works
flowchart LR
  A["Paper + supplements"] --> B["Evidence extraction"]
  B --> C["Compatibility hard gates"]
  C -->|supported| D["Typed PAER"]
  C -->|insufficient evidence| X["Evidence report + refusal"]
  D --> E["Symbols · units · provenance"]
  E --> F["Reference simulation"]
  F --> G["Reproduction checks"]
  G --> H["Allowlisted renderer"]
  H --> I["Offline experiment studio"]
Codex performs the evidence-aware interpretation inside the authenticated task. The bundled compiler scripts then handle extraction, validation, units, numerical reference execution, rendering, packaging and local serving with deterministic local code.
Built with Codex and GPT-5.6
PaperAlive was designed and implemented during OpenAI Build Week as a Codex-native developer tool. GPT-5.6 in Codex was an active engineering and scientific-reasoning collaborator throughout the primary build task—not a decorative mention added to the submission. Codex carried the project from the product specification through architecture, plugin implementation, scientific guardrails, the offline experiment studio, real-paper evaluation, packaging, documentation and release verification.
Where Codex accelerated the workflow
| Workstream | How Codex and GPT-5.6 were used | Evidence in this release |
|---|---|---|
| Product architecture | Converted the product brief into an explicit compiler pipeline: bounded evidence extraction, compatibility gates, a typed intermediate representation, deterministic validation, independent reference execution and allowlisted rendering. | PaperAlive skill, scientific method |
| Scientific reasoning | Traced equations, symbols, parameter tables, units, initial conditions, source locations, solver settings and reproduction targets without treating a plausible guess as evidence. | PAER authoring rules, support matrix |
| Safety and failure behavior | Translated scientific-honesty requirements into hard gates: no inferred critical quantities, no author-code execution, no arbitrary executable expressions, no unsupported renderer generation and no silent downgrade of trust. | failure policy, deterministic compiler scripts |
| Plugin engineering | Implemented and iterated on the portable Codex skill, extraction and validation CLIs, unit checking, independent reference simulation, static viewer build, package creation and loopback-only preview server. | installable plugin, manifest |
| Product and interaction design | Refined the experiment studio around synchronized equation, parameter, plot, spatial and source-evidence navigation; baseline comparison; time control; explicit trust; limitations; and offline exports. | bundled static viewer under plugin assets |
| Evaluation and release | Used a real open-access Repressilator paper to exercise the complete path, audited the output, prepared the focused no-build release and documented a judge-friendly installation and test route. | sample paper and PAER, this README |
Key product and engineering decisions made with GPT-5.6 in Codex
- Build a scientific compiler, not a free-form visualization generator. PaperAlive introduces PAER as a typed boundary between semantic paper understanding and execution, so a visually convincing scene can never substitute for a complete model.
- Make honest refusal a first-class product result. Missing central equations, parameters, units, initial/boundary conditions, provenance or an allowlisted adapter produces a precise evidence report instead of an invented simulation.
- Use one canonical schema. The bundled JSON Schema is the source of truth for the experiment contract; every later stage consumes the same typed structure.
- Separate model reasoning from numerical trust. GPT-5.6 interprets bounded evidence and authors the typed candidate. Local validators and independent numerical solvers—not the language model—derive structural, dimensional, reproduction and trust outcomes.
- Close every executable surface. Equation nodes, solvers, adapters and renderers come from fixed allowlists. The plugin never executes notebook cells, author code, model-generated functions,
eval, arbitrary HTML or arbitrary shaders. - Keep the delivered experiment local and portable. Once the plugin and pinned Python dependencies are installed, compilation, validation, simulation, rendering, packaging and viewing require no OpenAI API key, hosted model endpoint, backend, CDN, analytics service or font host.
- Treat provenance as interface state. Evidence is not a footnote: quantitative controls and outputs must resolve to source anchors, and the viewer exposes that path to the user.
How GPT-5.6 is integrated into PaperAlive
When a user invokes $paperalive in an authenticated Codex task, GPT-5.6 performs the semantic stage that a fixed parser cannot reliably complete:
- read the bounded, hashed extraction produced by the local tool;
- resolve notation and map prose, equations and tables into an explicit symbol table;
- distinguish directly reported, transparently derived and missing quantities;
- produce the Compatibility Report and select only a supported adapter;
- author a PAER candidate with evidence anchors and status links for every quantitative element;
- repair a candidate only where the evidence determines a unique correction;
- explain ambiguity and stop when a critical scientific gap remains.
The output of that reasoning is not trusted merely because the model produced it. Deterministic local code then owns the pass/fail path:
flowchart LR
  A["GPT-5.6 in Codex: bounded evidence interpretation"] --> B["Typed PAER candidate"]
  B --> C["Local schema, symbol, unit and provenance gates"]
  C --> D["Independent reference simulation"]
  D --> E["Declared reproduction and invariant checks"]
  E --> F["Allowlisted offline renderer and package"]
GPT-5.6 does not assign trust by assertion, silently fill missing science, execute the authors' code, create arbitrary renderer geometry, calculate the reference result, or run inside the exported viewer. This division of labor is the core of the product: GPT-5.6 contributes high-value semantic interpretation, while every decision that can be made deterministically remains reproducible and auditable.
Concrete Build Week workflow
The primary Codex task was used for the majority of core development and its /feedback Session ID is supplied to judges in the private Devpost field. A representative end-user task is:
$paperalive Compile this paper into a validated interactive experiment.
For the included Repressilator source, Codex reads the paper evidence and orchestrates the plugin. The local tools create the extracted evidence, Compatibility Report, canonical .paperalive.json, validation and unit reports, independent numerical reference, static site and portable offline ZIP. The included reviewed PAER and paper let judges inspect this route without inventing sample data or rebuilding a frontend.
The public repository is intentionally the focused, installable release. It contains the complete runtime plugin, pinned dependency list, prebuilt offline viewer, canonical schema, example source/PAER and licensing material; development caches and the larger internal test monorepo are excluded from the judge download.
The compiler currently supports three deliberately narrow adapters:
| Adapter | Intended use | Interactive representation |
|---|---|---|
ode-system-v1 | Coupled deterministic ODEs | Time series and mathematically labelled phase space |
particle-system-v1 | Deterministic particle dynamics | Physical trajectories and state inspection |
scalar-field-v1 | Quantitative fields on a fixed grid | Heatmap, contours and surface views |
Scientific honesty first
PaperAlive uses explicit compatibility outcomes:
SUPPORTED_AUTOMATICSUPPORTED_WITH_REVIEWILLUSTRATIVE_ONLYUNSUPPORTED
Its trust hierarchy is equally explicit:
| Trust | Meaning |
|---|---|
| A | Computationally Reproduced |
| B | Independently Reimplemented |
| C | Verified Interactive Model |
| D | Illustrative Interpretation |
| X | Unsupported |
Missing central equations, parameters, units, initial conditions or provenance are hard gates. PaperAlive never silently fills them with plausible values. Quantitative controls and outputs must have source evidence or be clearly marked as derived exploration.
What the plugin produces
For a supported paper, a successful run produces:
work/
├── extracted/                         # hashed evidence and source locations
├── experiment.paperalive.json         # canonical typed experiment model
├── validation.json                    # structural and semantic gates
├── units.json                         # dimensional validation
├── reference/                         # independent numerical results
├── site/                              # static offline experiment studio
└── experiment.paperalive.zip          # portable package
The viewer provides interactive controls, baseline comparison, synchronized plots and spatial views where scientifically meaningful, evidence drawers, limitations, validation status and downloadable audit artifacts.
Local-first by design
The installed plugin and generated experiment require:
- no OpenAI API key;
- no hosted model call at runtime;
- no backend or database;
- no CDN or remote font host;
- no author-code execution;
- no
evalor generated executable expressions.
The viewer is prebuilt and bundled with the plugin. Numerical simulation runs independently of the camera, render interpolation and frame rate. The generated preview server binds only to 127.0.0.1, chooses a free port, verifies the response and prints the exact stop command.
Repository layout
.agents/plugins/marketplace.json        # Codex marketplace entry
plugins/paperalive/
├── .codex-plugin/plugin.json           # plugin manifest
├── skills/paperalive/                   # workflow, method and compiler scripts
└── assets/                              # canonical schema + offline viewer
examples/repressilator/                  # real CC BY paper + reviewed PAER
docs/                                    # public project visuals
This is the focused, installable release repository. It intentionally excludes the full development monorepo, build caches and internal test fixtures.
Scope and limitations
PaperAlive v1 is for sufficiently complete, text-based quantitative papers. It does not execute notebook cells or author code, infer missing coordinates, provide clinical advice, or pretend that arbitrary CFD, FEM, chemistry or black-box machine-learning papers are supported.
Scientific implementation verification is not the same as real-world validation. PaperAlive only claims observation-level validation when appropriate measurement evidence is present in the source.
License
PaperAlive code is released under the MIT License. Third-party packages retain their upstream licenses. The included PLOS paper is distributed under CC BY 4.0 with attribution; see Third-party notices.
PaperAlive makes scientific models explorable without making them less accountable.
Analysis
View
Metric
- 2

Figures cover GitHub contributors during the hackathon window. A co-authored commit counts in full for each author, so per-member totals add up to more than the whole-team figures.
Technology
- CSSIn code
- HTMLIn code
- JavaScriptIn code
- PythonIn code
- ReactClaimed
- TypeScriptClaimed
4 of 6 appear in the indexed code. 2 claimed on Devpost could not be matched to code, which may simply mean the tool leaves no trace in the repository.
AI coding agents
No AI coding agent signals were found in this repository.
Detected from committed agent config files and commit authorship. Absence of a signal is not proof an agent was unused.
Codebase size
Source size
7.2 MB
Source files
31
Counts recognized source files only; vendored directories, binaries and lockfiles are excluded, so this is smaller than the repository on disk.
Repository
victus17/paperalive-codex-plugin
51 files · 30.2 MB · @ d8df093
Structure
Application logic
5 files · 10%Domain rules, services and shared utilities.
Supporting
Layers are inferred from where files sit in the tree, not from reading the code. A project that names its directories unconventionally will read oddly here — open the file browser to check anything the diagram implies.
Languages
- JavaScript97%
- Python2%
- CSS1%
- Markdown1%
- HTML0%
Share of indexed source by file size. Binary and vendored files are excluded.
Dependencies
plugins/paperalive/assets/requirements.txt
pypi · 9- hypothesis
- jsonschema
- numpy
- pint
- PyMuPDF
- pytest
- PyYAML
- ruff
- scipy
Declared in the repository’s manifests at the indexed commit. A declared package is not proof it is used, and runtime dependencies are listed first.
This project’s features have not been analysed yet.
Export this project's context (description, README, evidence, key source files) to chat with an AI agent elsewhere.